;)
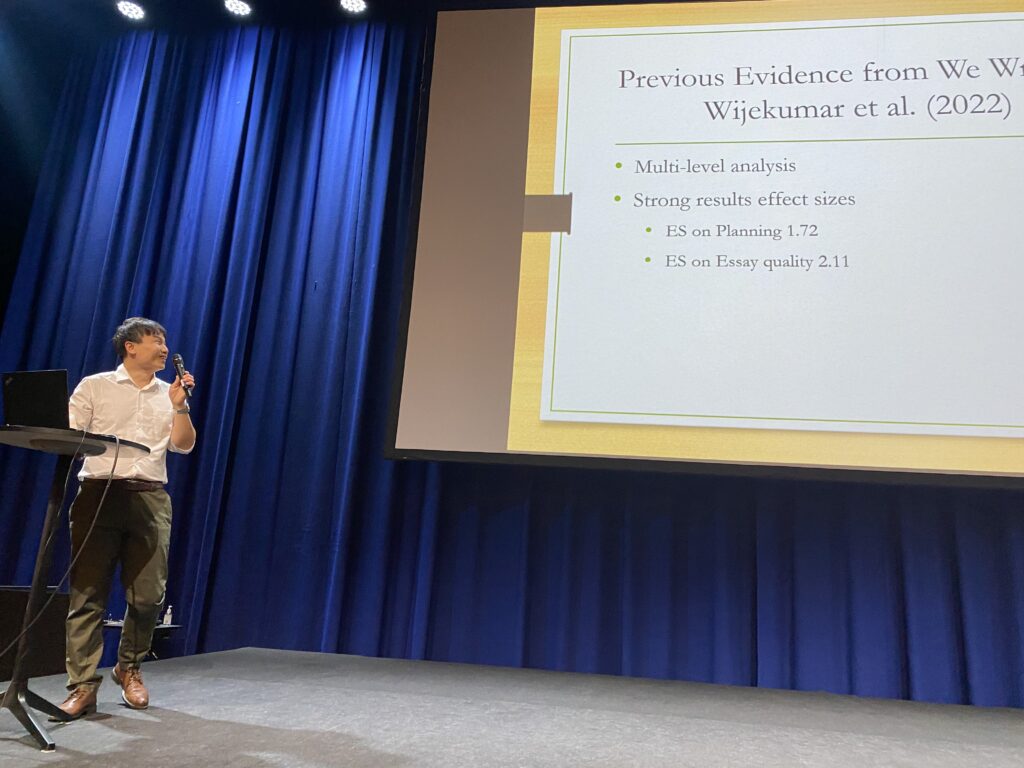
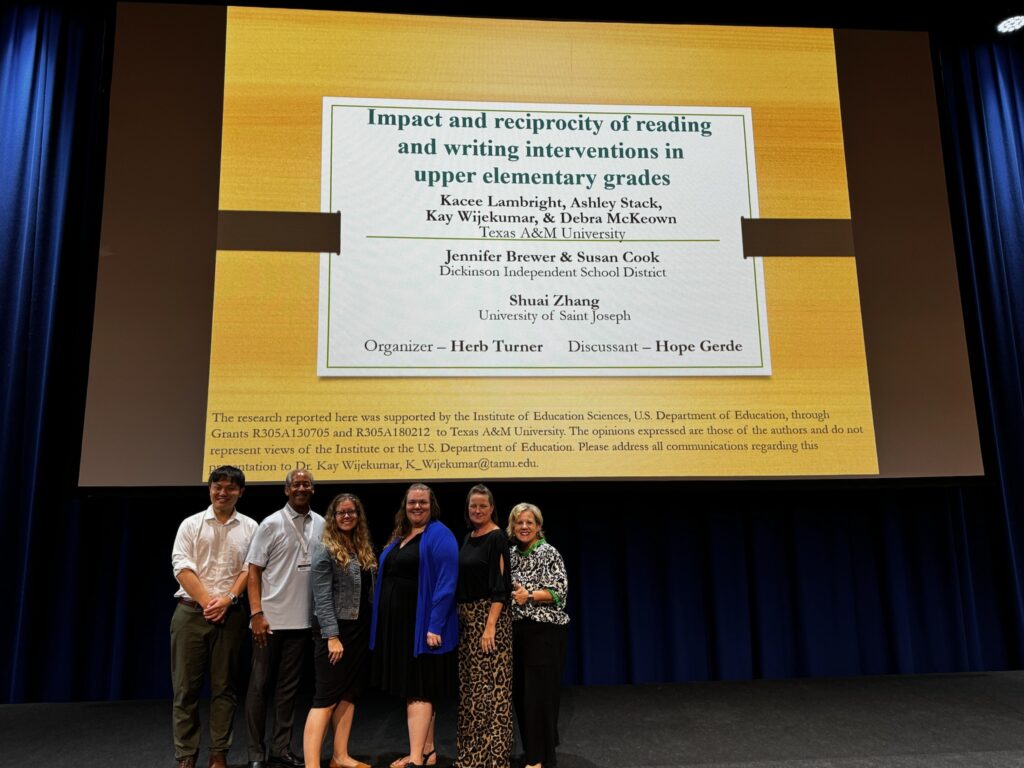
Dr. Zhang presented his work, titled Measurement of writing outcomes using large language models, in the symposium session titled “The Impact and Reciprocity of Reading and Writing in Upper Elementary Grades.”
Dr. Zhang’s Summary of his Presentation:
In this presentation, I shared with the research community the reliability of AI-based essay scoring when compared to teacher scoring in upper elementary schools. Using 1300+ essays, we compared how AI-scoring, operated by ChatGPT, would be different from teacher scoring on the same persuasive essays among 4th and 5th-grade students. We found that while teachers reported sometimes having inconsistent scoring due to scoring fatigue, AI scoring has a long way to go before it can be fully applied in school settings. This was evidenced by less than 27% of essays being scored the same between teachers and ChatGPT. However, eventually, we will endeavor to make AI scoring more reliable so teachers can focus on instruction and feedback but less on scoring.
Congratulations, Dr. Zhang!